Source
https://live.bytebytego.com/courses/ai-evals
Category
File Size
4 GB
Publisher
bytebytego
Updated
November 14, 2026
Description
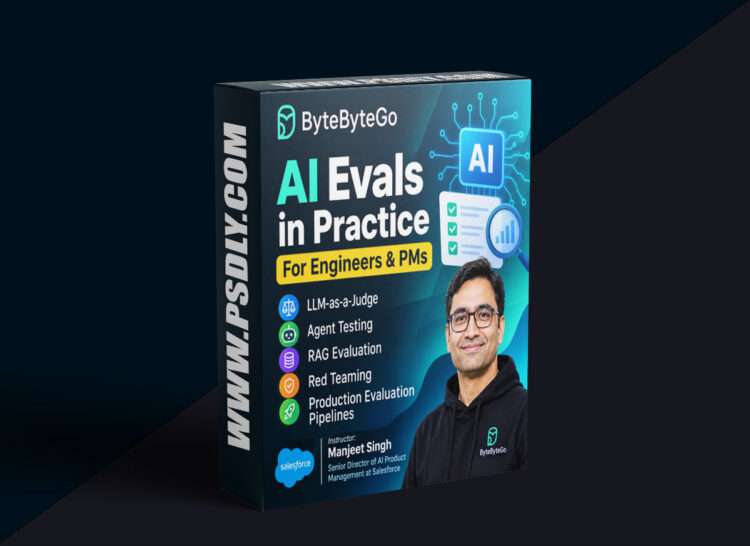
A practical course dedicated to evaluating the quality, reliability, and safety of artificial intelligence, large language models (LLM), and autonomous AI agents
What you’ll learn
- Understand how AI evals work
- Learn why unit tests and traditional QA break on non-deterministic systems
- Measure AI quality like accuracy, safety, reliability, cost, and latency
- Turn real failures into your first evals with error analysis
- Take a multi-step agent trace and find where it went wrong in minutes, not days.
- Build LLM judges you trust
- Grade outputs automatically with LLM-as-a-Judge
- Write pass/fail rubrics that behave like assertions
- Validate every judge against human review before relying on it
- Red-team agents before attackers do
- Attack your own agent with prompt injection and jailbreaks
- Automate red teaming with Promptfoo
- Add guardrails that block attacks without blocking real users
- Put your agent through a safety and adversarial review your security team takes seriously.
- Build meaningful eval datasets
- Build golden datasets from real traffic plus validated synthetic data
- Version datasets like code so results stay reproducible
- Score RAG pipelines with the RAGAS metrics
- Evaluate agents on different dimensions
- Test whether agents call the right tools with the right arguments
- Judge the agent’s full trajectory and final answer
- Catch failures hiding in multi-agent handoffs
- Run evals in production
- Wire evals into CI/CD so regressions never merge
- Monitor live traffic
- Catch model and data drift
- Ship a complete eval system
- Take a capstone from untested agent to gated, monitored pipeline
- Pick the cheapest model that still meets your quality bar
- Turn every incident into a permanent regression test
Preview
1 image
Download File